Serve the features you trained on.
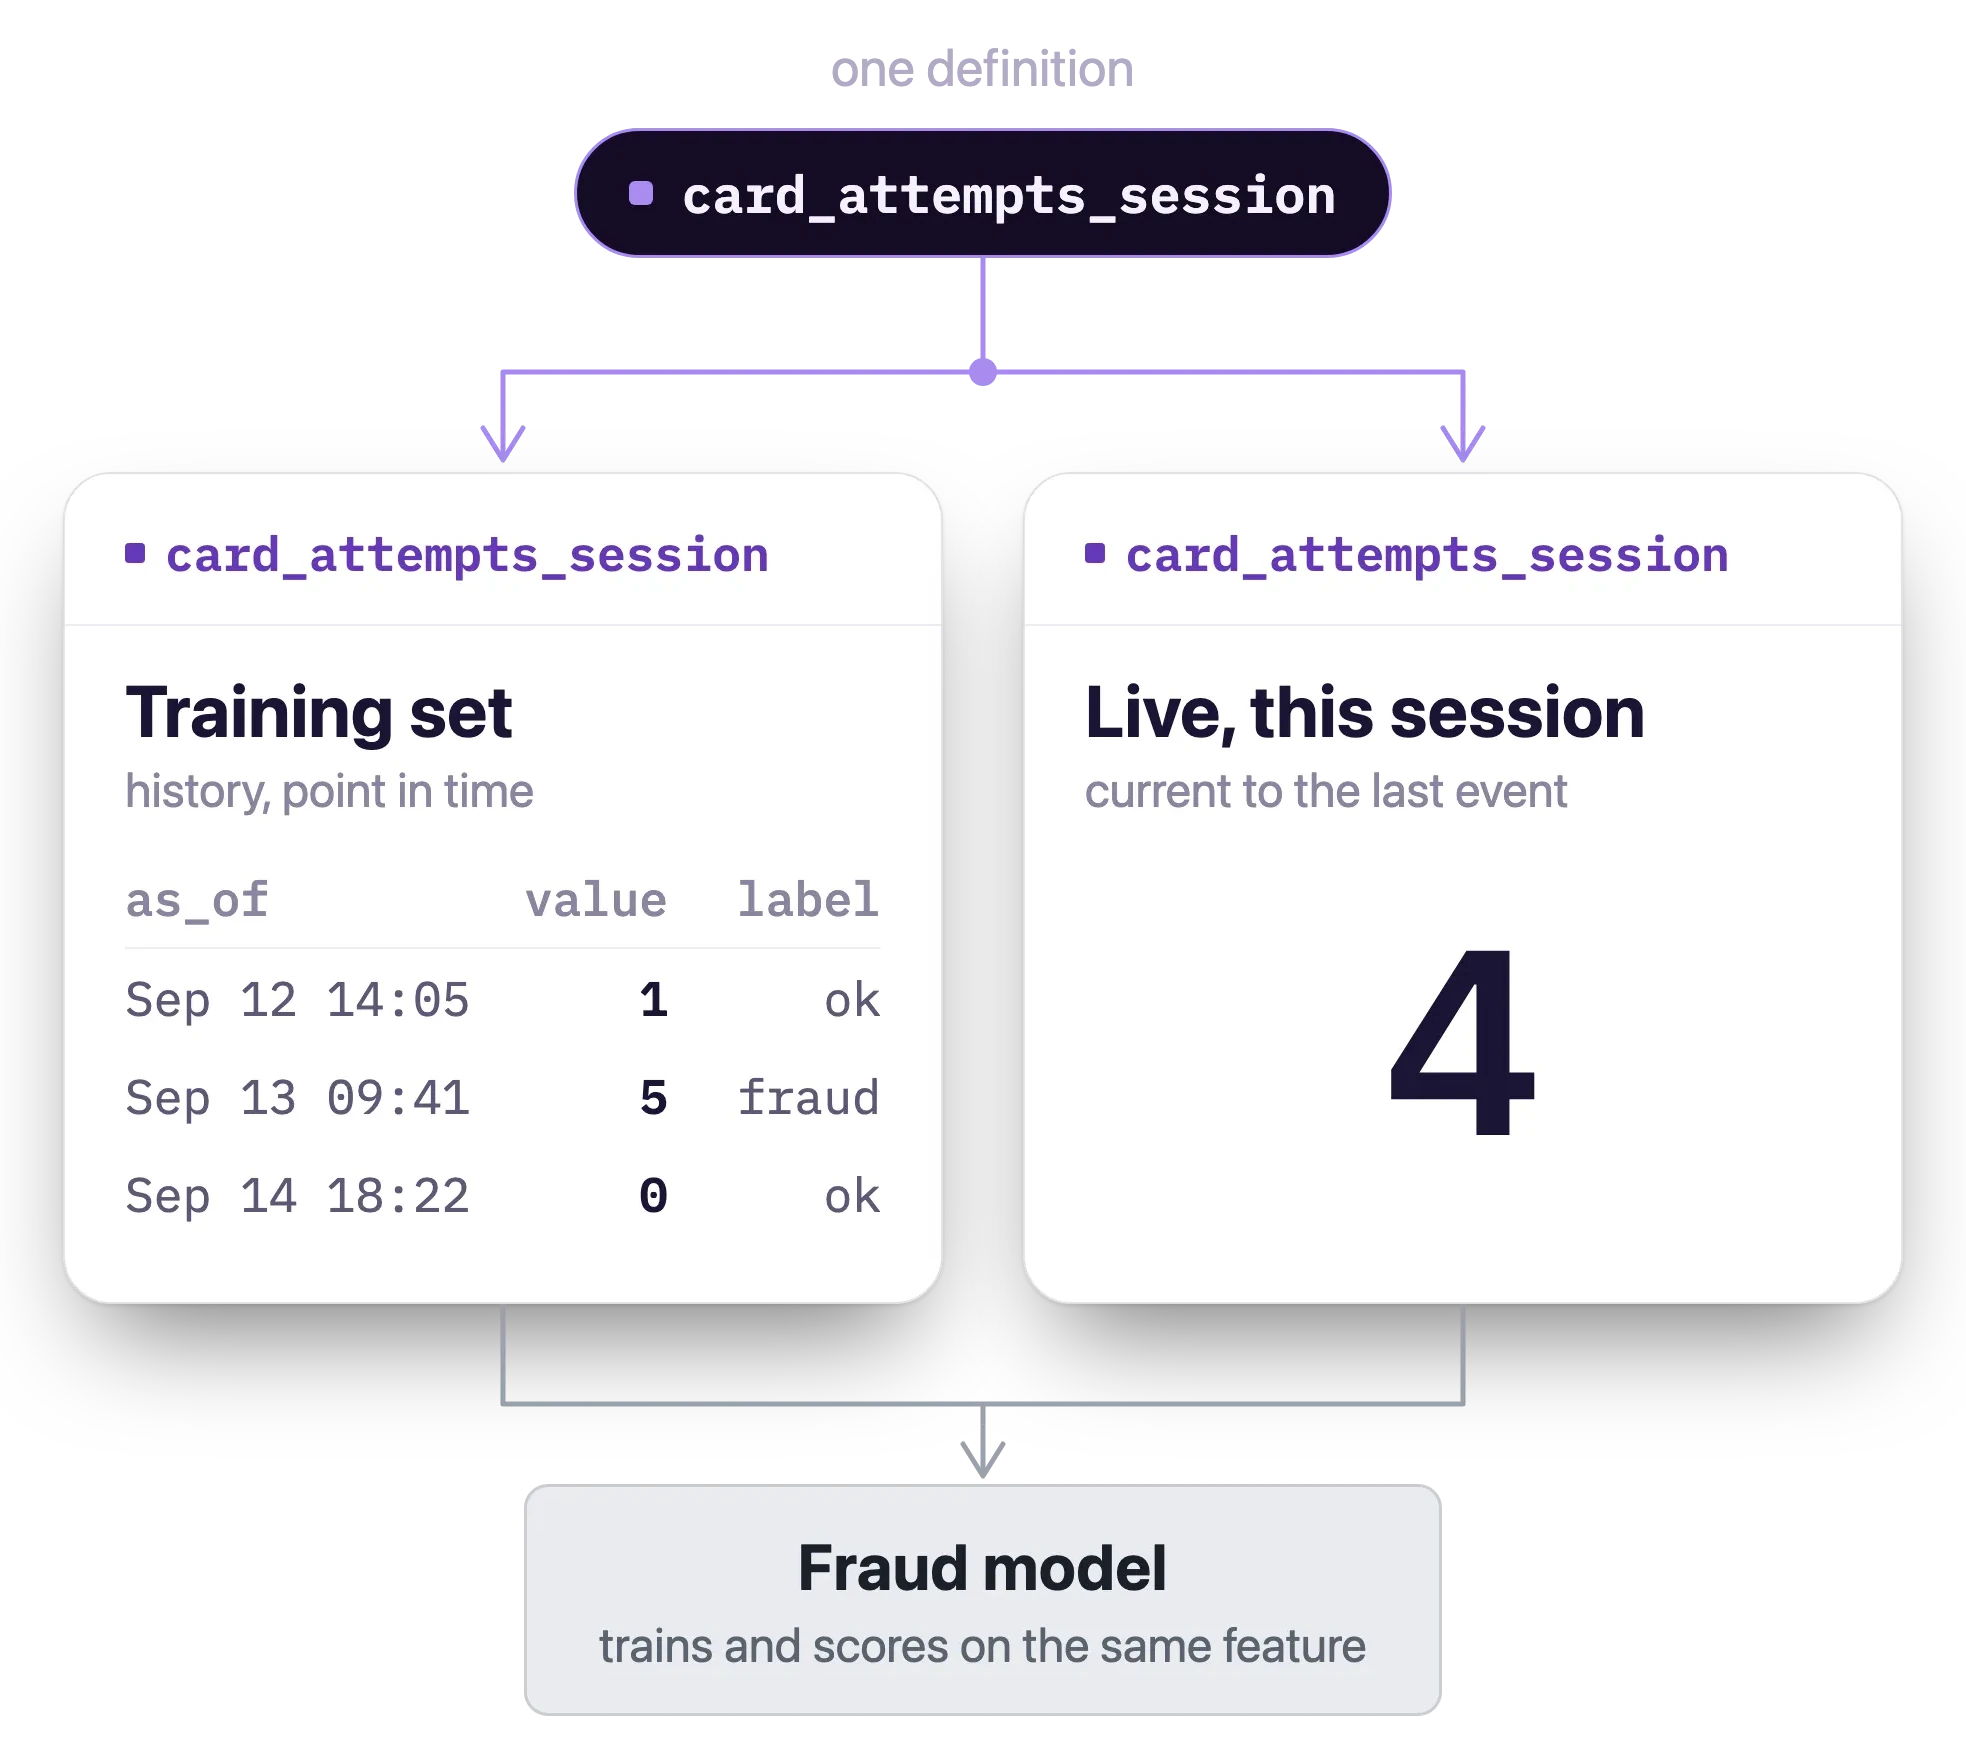
A model trained on the notebook's version of a feature and served a production rewrite drifts without anyone noticing. Signals builds the training set and serves the live value from one definition, so what the model learned from is what it reads at inference.
Below is your own visit to this page, computed by Signals as you read.
Signals, about you
connectingSignals is computing your first attributes from the events this page just sent.
Every highlighted part is an attribute Signals computed from the behavioral data your browser sent during this visit. Open the Product menu above and watch the sentence change.
Notebook features stall on the way to production.
Someone rewrites the feature for serving, the two drift apart, and the model degrades without anyone noticing.
Models that score this session, on the features they learned from.
Each of these needs the feature current to the last event at inference, and the same feature as it stood at each past moment for training.
Higher model lift
The score runs on features from before the session. Signals serves the same features current to the last event, so the score can still change the outcome.
Offline gains that hold online
The ranker trains on features production cannot reproduce. Signals builds both from one definition, so what you measured offline is what you get live.
Lower losses before payout
Abuse is caught in the next review, after the money has moved. Signals serves this session's behavior to your model at request time, so it scores before the payout.
Define once. Train on history, serve on the stream.
Add a Snowplow SDK
Web, mobile or server. Events arrive validated against your schemas, so every feature reads clean, typed properties.
Write the feature as an attribute
Signals calls each feature an attribute. Counts, recency and order over your events, keyed on user, session or listing.
Build the training set from the same definition
Name the outcome. The dataset builder labels your history and computes each attribute as it stood at that moment, into a table in Snowflake.
Read it at inference from the streaming engine
One call returns every feature in the service, in 6ms p50, in-region.
Step by step: Score prospects with a live model →The background: Feature stores, explained →
- Snowflake
- Databricks
- BigQuery
- Vertex AI
- Amazon Bedrock
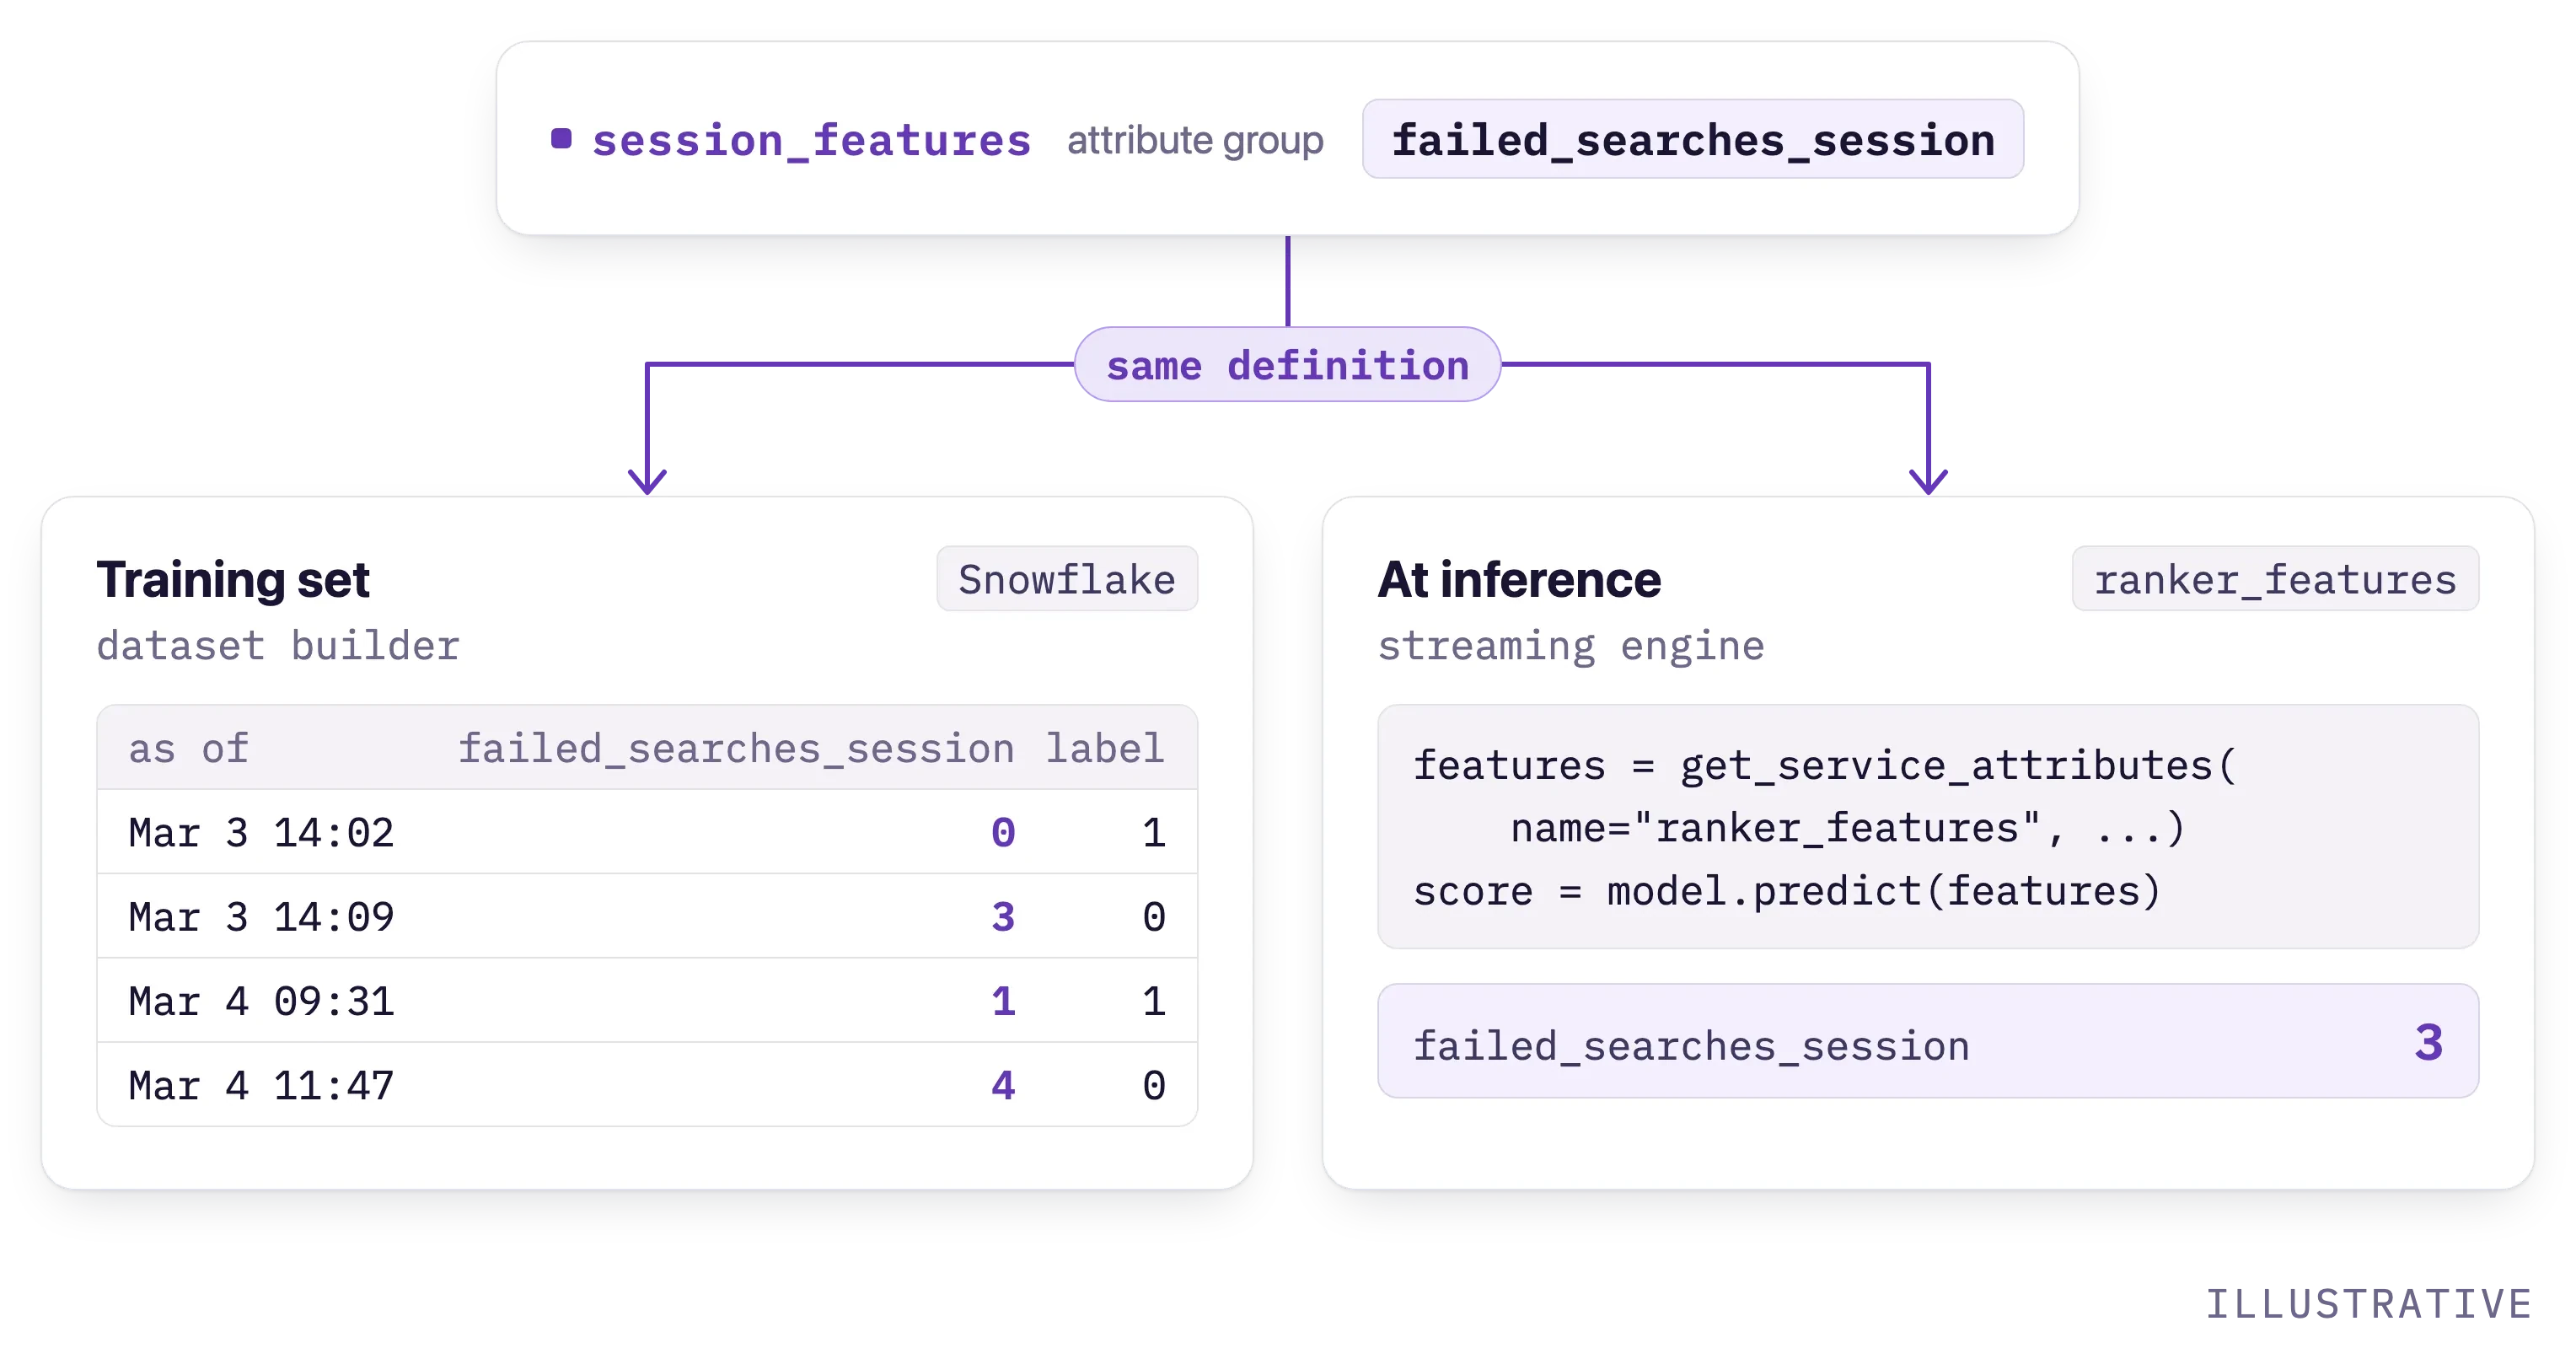
The same attribute group, in the training set and at inference.
The Python SDK builds a point-in-time correct training set from your attribute groups, then reads the live values from the service that holds those same groups.
npx plugins add snowplow/skillsfrom datetime import datetime, timezone
from snowplow_signals import AtomicProperty, Criteria, Criterion, Signals, TrainingSpan
sp_signals = Signals(api_url=api_url, api_key=api_key, api_key_id=api_key_id, org_id=org_id)
# Training: one row per labeled moment, features from only the events before it.
run = sp_signals.submit_dataset_run_with_session_anchors(
attribute_groups=[session_features],
goal_criteria=Criteria(all=[
Criterion.eq(AtomicProperty(name="event"), "transaction"),
]),
training_span=TrainingSpan(
start_time=datetime(2026, 1, 1, tzinfo=timezone.utc),
end_time=datetime(2026, 4, 1, tzinfo=timezone.utc),
),
)
# Inference: the same features, current to the last event.
features = sp_signals.get_service_attributes(
name="ranker_features",
attribute_key="domain_sessionid",
identifier=session_id,
)
score = model.predict(features)Add Snowplow Signals to this model's pipeline so training and serving use one feature definition. Rewrite the session features from our notebook as a Signals attribute group, build the training set with submit_dataset_run_with_session_anchors using our conversion event as the goal, and replace the serving path's feature code with get_service_attributes. Keep the model and its hyperparameters as they are, so the only thing that changes is where the features come from.
The dataset builder supports Snowflake today. You can run a managed build, or generate the SQL and run it yourself.
The feature: Real-time attributes →Full reference: Create ML training datasets →
The model sees what it was trained on.
Shared by the training set and live serving
Second implementation of a feature for your team to maintain
Added at inference, p50 in-region
Before you move a feature over
Is this a feature store?
It does the serving half of one for behavioral features, and it builds the training set from the same definitions. It starts from the events, so it collects them too. If your features come from other sources, a general feature store may suit you better.
Do I have to replace the feature store I run?
No. A common pattern is Signals for behavioral features on the request path and your existing store for everything else.
How does it stop training data leaking the outcome?
The dataset builder computes each attribute from only the events before the moment you are predicting from, using the same definitions the live path reads. Nothing that happened afterwards reaches the training row.
Which warehouses does the dataset builder support?
Snowflake today. Attribute backfill, which fills history into the live store, also runs from BigQuery and Databricks.
Do I need an event stream already?
No. Collection is part of Signals. Add a Snowplow SDK and events start flowing. If you already run Snowplow, Signals reads the pipeline you have.
Where does it run?
Managed SaaS, or a private deployment in your own AWS or GCP account. Same architecture either way.
Move one feature out of the notebook.
Define one feature as an attribute, build a training set from it, then read the same value live for your own sessions. The free tier runs on the real engine: no card, no sales call.