Real-time intent, without the data science
Intent is five buckets. You do not need a propensity model to sort into them.
A propensity model is a quarter of feature pipelines and training data before the first score. Sorting a visitor into browsing, comparing, hesitating, ready or stuck is a typed question. Signals supplies the live state, Jev answers it, your code acts, all inside the session.
- 6ms p50 read, in-region
- 0 models to train
- Free tier, no card
Teams running on Snowplow
The model below is deciding about your visit as you read.
A model, about you
connectingWhat a System One model decides about you and your visit, right now
Signals is computing your visit from the events, we will ask Jev about it next.
Browse around the site, come back, and watch both answers move.
Who · Jev's confidence in each rolewaiting for the first answerWhat · Jev's confidence in each intentwaiting for the first answer
Keyed on an anonymous session id. Jev is asked again each time your visit changes.
Why intent never goes live
Most intent projects never ship. The data science is why.
Before
A propensity model with a launch date
Labeled training data, a feature pipeline, offline validation, a serving path, then a quarter of chasing why production scores disagree with the notebook. Most teams never reach the part where the score changes what a customer sees.
p(convert) = pendingWith Signals
A typed question over live state
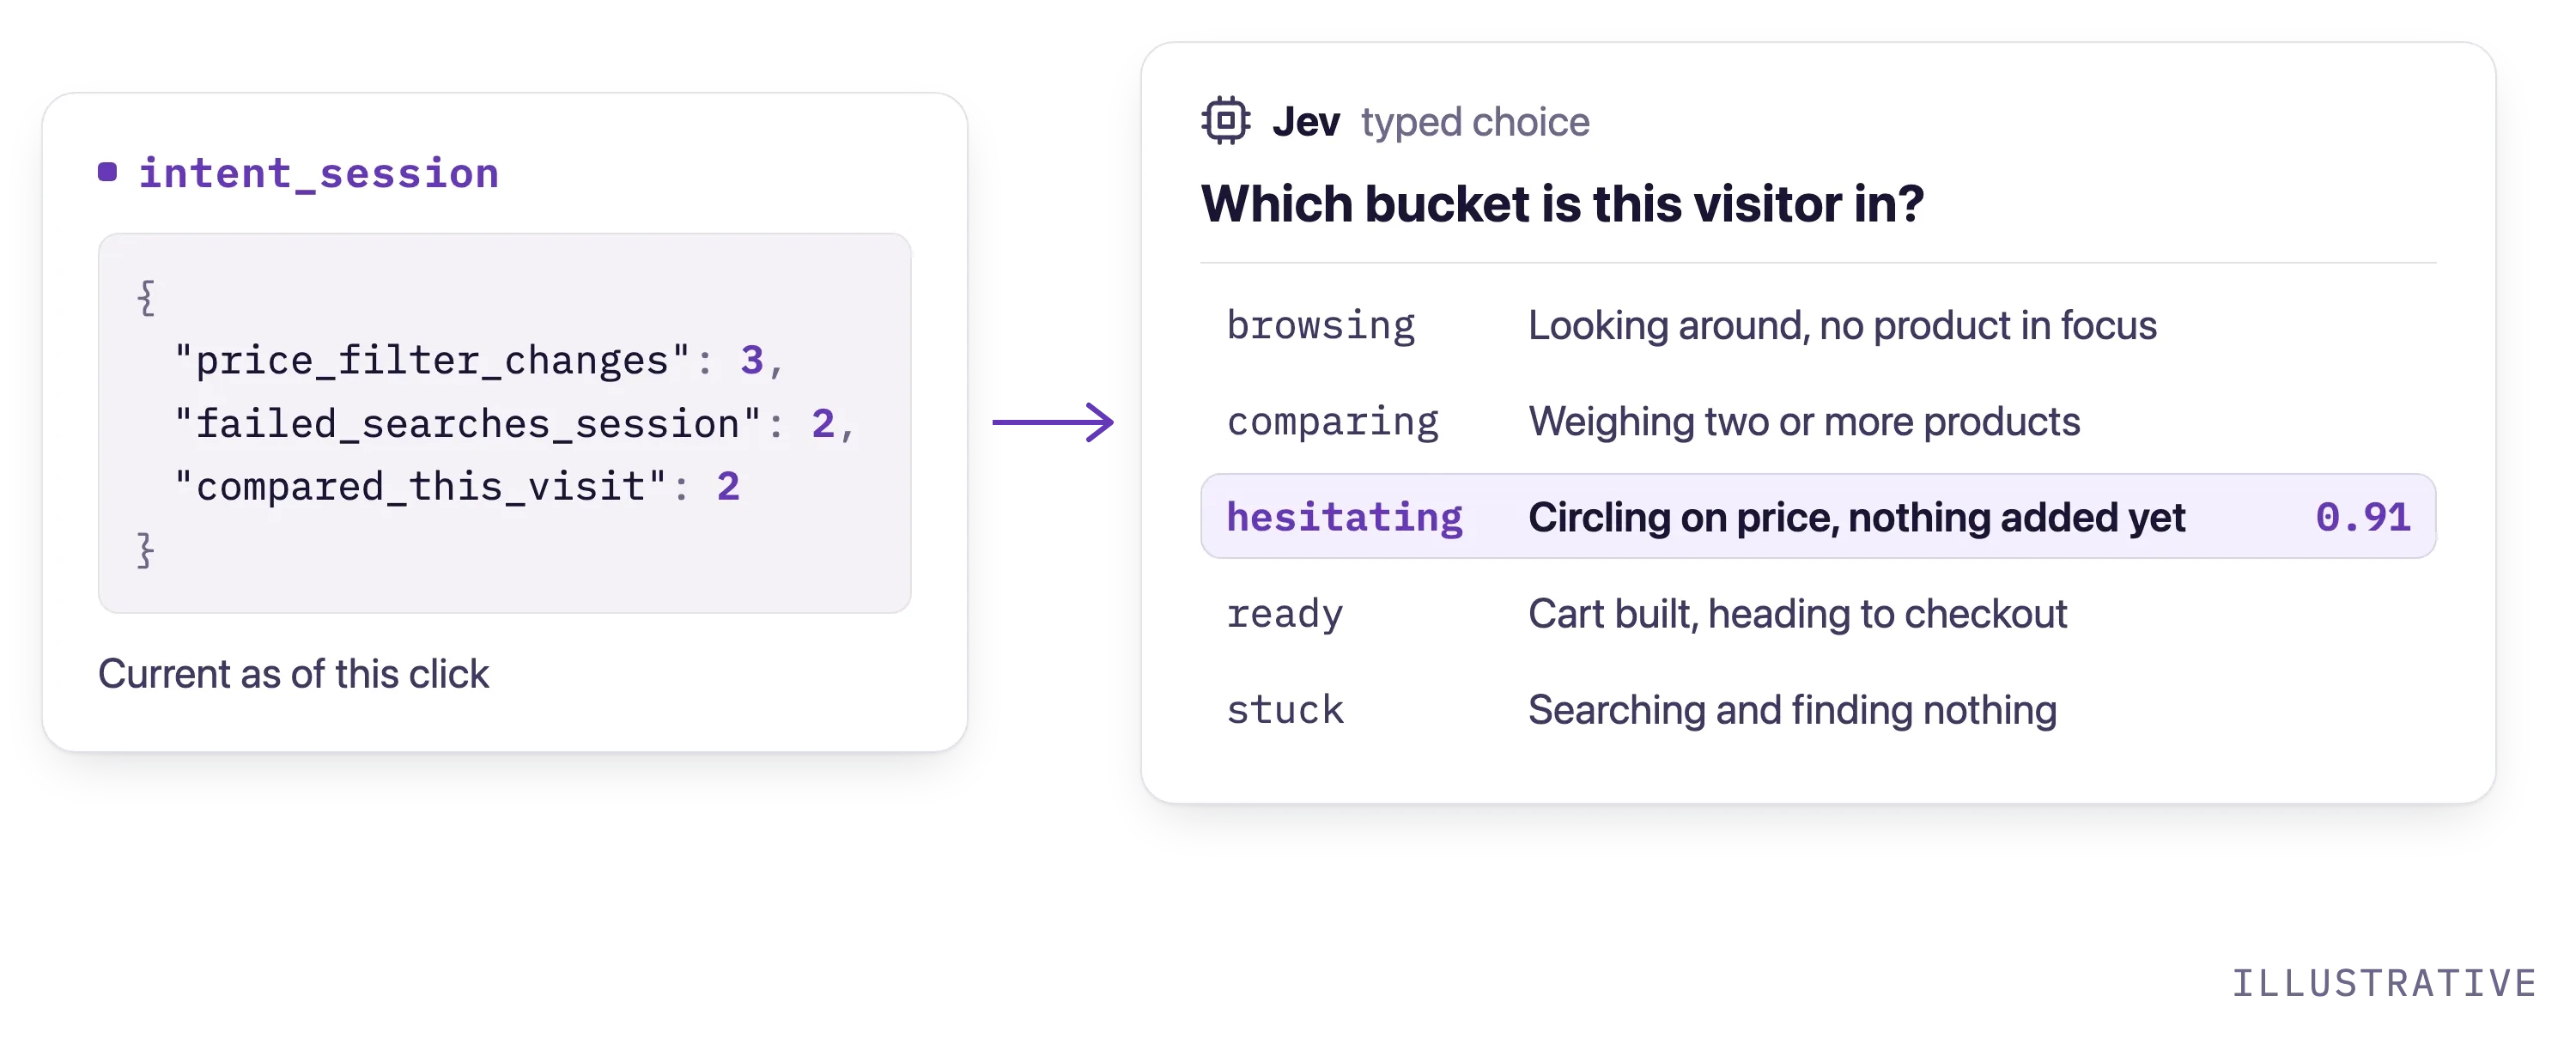
Signals computes what this visitor has been doing, current as of this click. Jev answers which of your five buckets describes them, with a probability you can gate on. No training set, because the buckets are the definition.
intent = hesitating (0.91)Result
Live on your own traffic today
The bucket drives the render, the offer, the route. When a bucket turns out to be wrong you change the words that define it, not a model.
same session, acted onWhy buckets beat scores here
What changes when intent is a choice, not a score.
Recommenders earn their keep picking ten items from ten million. Deciding which of five states a visitor is in was never that problem, and treating it like one is why it stays next quarter.
Ship today, not next quarter
No labels to collect, no features to engineer, no model to validate. The buckets are written in plain English, the state is live, and one prompt to your coding agent wires the first answer to run against a real visitor on the free tier.
time to first live segmentExplain every decision
A score of 0.62 tells nobody why. "Comparing two products, third price filter change" does. Product, marketing and support read the same bucket and agree on what to do about it.
decisions acted on · time to agree a ruleChange the buckets in a pull request
When hesitating turns out to be two different things, split it and ship. A propensity model needs a retrain and a revalidation for the same change.
iterations per monthKeep the recommender for what it is good at
Ranking a catalog stays with the model built to rank a catalog. Intent tells it, and everything else on the page, which mode this visitor is in.
click-through per bucketHow it works
Name the buckets. Signals supplies the state. Jev picks one.
Signals computes what this visitor is doing. The typed question does the sorting. Your code does the acting, with a probability to gate on.
- 01Collect. Add a Snowplow SDK to your app and behavioral events start flowing in, validated on the way.
- 02Read. One call returns what this visitor has been doing as JSON, <1s after the event, in 6ms p50.
- 03Sort. Ask Jev a typed choice over your buckets, gate on the probability, act on the answer in the same render.
Signals → your app6ms p50
nameintent_session
formatjson
price_filter_changes3
failed_searches_session2
compared_this_visit2
Trigger stuck_visitordelivered to your app
Works with
- Jev
- LangChain
- LangGraph
- LlamaIndex
- CrewAI
- OpenAI Agents SDK
- Vercel AI SDK
- Mastra
- Pydantic AI
- Google ADK
- CopilotKit
- Braze
Questions
Before you sign up
Is this personalization?
It is the part of it that usually stalls, knowing what the visitor is doing right now. Signals computes that live state, the typed question does the sorting, and whatever you already use to act, your own code, a rules engine or a messaging tool, keeps doing the acting.
When is a propensity model the right call?
When the question has ten million answers. Choosing which items to show from a large catalog is a ranking problem and a recommender is the right tool for it. Sorting a visitor into a finite set of states is a classification with a handful of answers, and a typed question over live state does it without the training pipeline.
How do I know the bucket is right?
The answer comes back with a probability calibrated against the state you sent, so you choose the threshold at which your code acts and do the default below it. Keeping the state current to this visit is what Signals is for. TypeSafe's own documentation says accuracy falls as state fills with material the question does not need, which is why the context is named and filtered before the call.
Does this only work with Jev?
No. The context comes back as JSON over the REST API, the Node.js or Python SDK, or the MCP server, and as a plain string in narrative form. Anything that takes a state object or a prompt can read it. Jev is the model this page is written for because a typed choice with a probability is exactly the shape a bucket needs.
Do I need an event stream already?
No. Collection is part of Signals. Add a Snowplow SDK to your web, mobile or server app and events start flowing in. If you already run Snowplow, Signals reads the pipeline you have.
What does the free tier include?
The full product against your own traffic, up to 5 million events a month, with no card and no sales call. You should see an attribute updating against your own traffic in the first session.
Sort your own visitors into buckets today.
Add the SDK, define one context, write five buckets in plain English and ask. The panel at the top of this page is that question, running on you as you read.
The real engine · no card · no sales call
Or hand it to your coding agent
Then: Add Snowplow Signals to this app. Define an agentic context for what a visitor has been doing this session, read it as JSON, and ask Jev a typed choice that sorts them into browsing, comparing, hesitating, ready or stuck. Gate on the probability and act on the answer where we render.npx plugins add snowplow/skills