Earlier this year I wrote that brand-owned, customer-facing agents have a problem third-party and back-office agents do not: the behavior context gap. The agent only knows what the user types, so the user has to re-explain a journey the website already watched them take. The tutorial that followed closed that gap on a Next.js app we wrote ourselves, where every tool was a TypeScript function we controlled.
Most teams building customer-facing agents are not in that position. They are building on a managed platform, where the agent runtime, the tool-calling loop and the chat widget belong to the vendor, and the integration points are an OpenAPI schema and a prompt.
This post is about closing the context gap on exactly that kind of platform: Google’s Gemini Enterprise for CX, specifically CX Agent Studio. It is one half of a reference integration we have open-sourced under the Apache 2.0 license. The other half, where the same agent tracks its own reasoning back into the pipeline, is in the same repository. The build, with its code and a recording of it running, is on its reference architecture page.
What the shopper sees
The storefront is Atelier Signals, a fictional luxury fashion house. A visitor lands on it with no account and no login. They browse a Maison Cendre blazer, add it to the cart, look at a silk column dress and a cashmere wrap coat, then open the concierge and type “Hi, I’m looking for something to finish an evening look”.
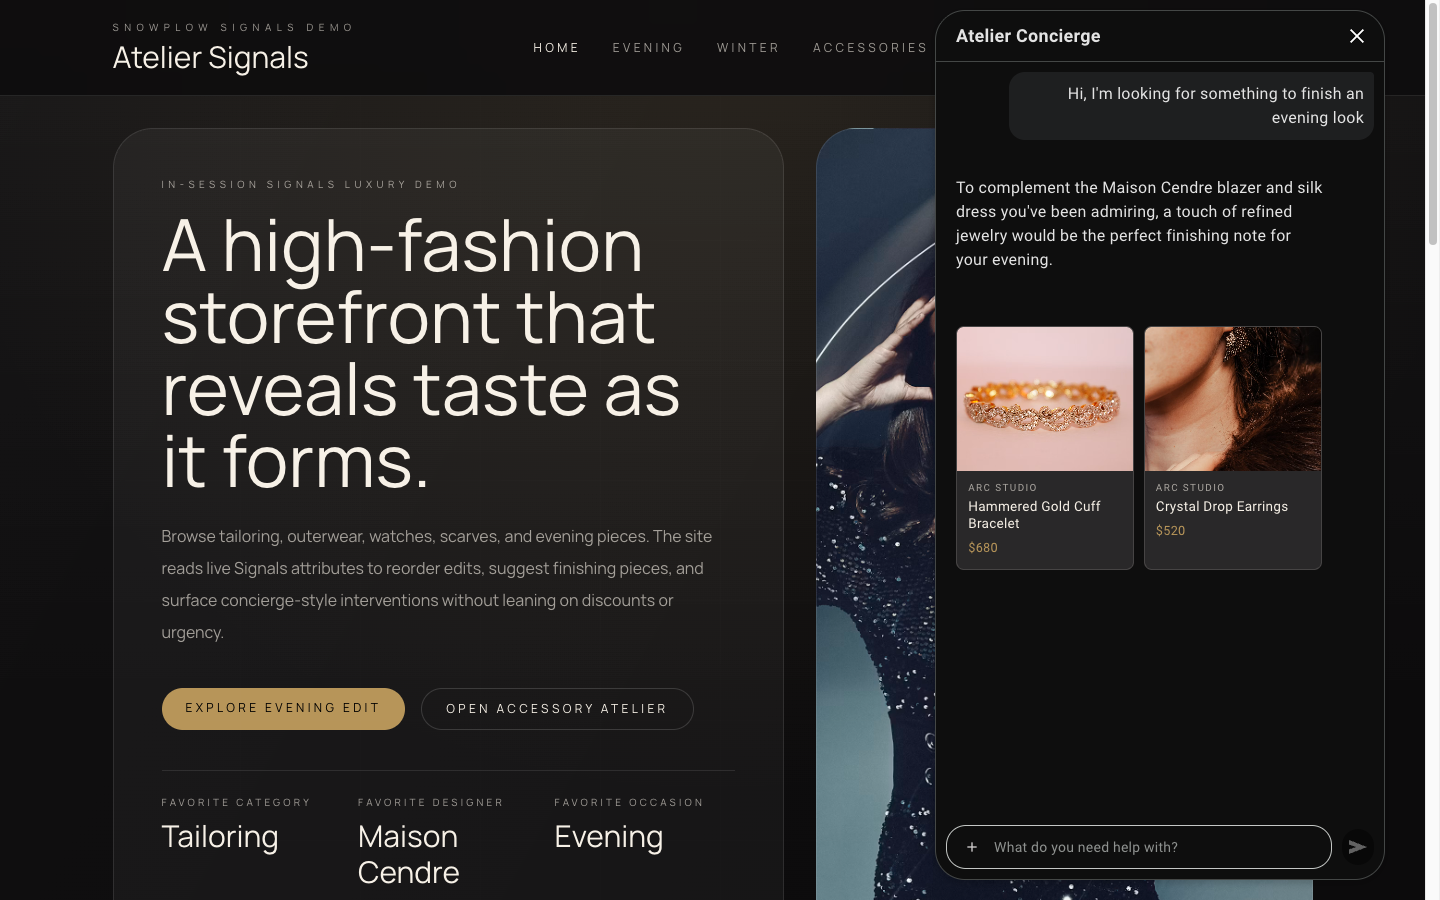
The agent’s first reply refers to the Maison Cendre blazer and the silk dress the shopper browsed, and recommends two finishing pieces as product cards. Nobody typed “I was looking at a blazer”. The shopper is identified only by the Snowplow domain_sessionid cookie, the same cookie the storefront’s own tracking uses. If that cookie is missing, because the visitor is new or blocking cookies, the agent gets an empty profile and behaves like a concierge meeting a customer for the first time. It never says anything is missing.
That is the context gap closed. The agent starts its first reply from what the shopper has done in this visit, and the shopper never has to describe it.
How the pieces fit together

There are four moving parts.
The storefront is a Next.js app on Vercel. In the browser it runs the Snowplow JavaScript tracker for the usual ecommerce events (product_viewed, cart_updated, checkout_started and so on) and embeds Google’s ces-messenger chat widget, with a small hook that tracks message_sent and message_received for each conversation turn. On the server, its API routes double as the agent’s tools.
The Snowplow pipeline receives every event, from the browser and from the server. Signals computes per-session attributes from the stream and keeps an event log of recent activity. The BigQuery loader writes everything to the atomic events table.
The agent lives in CX Agent Studio and runs on Gemini. It has two business tools, getUserContext and searchCatalog, and a toolset of three self-tracking tools, all imported from OpenAPI schemas that point at the storefront’s API routes. Its instructions describe the concierge persona, when to call each tool, and the self-tracking protocol.
BigQuery holds the result, and a set of SQL files in the repo turns it into answers.
Getting session context to the agent at query time
Signals is configured from Python in the repo. One attribute group, keyed on domain_sessionid, computes the shopper’s taste profile in stream: favorite_designer, favorite_category, favorite_occasion and favorite_color_family, interest counts for each of those dimensions, recently_viewed_product_ids, high_intent_product_ids, and cart and checkout state such as cart_value_band and checkout_stage. Alongside it, a Signals event log called fashion_session_activity keeps the last hour of product views, cart changes and checkout starts for the session, and comes with a prompt that renders them as a short plain-language narrative in the third person.
The getUserContext tool wraps both. It takes the session ID, calls Signals, and returns three fields: profile (the flattened attributes), recent_activity (the narrative) and agent_instructions (interpretation guidance for the narrative). The agent is told to call it once at the start of a conversation before its first reply, and again on each turn so that anything the shopper browsed between messages is reflected.
We chose a tool call over a data store deliberately. CX Agent Studio’s data stores are built for knowledge: they are synced on a schedule and searched by relevance. A browsing session is minutes old and keyed by an ID. An OpenAPI tool that reads Signals at the moment the shopper sends a message is the right shape for that, and the context_lookup entity attached to every call records the Signals round trip time so you can watch what that choice costs.
Threading the shopper’s ID through a platform you do not control
The hard part of this integration was not Signals. It was getting the shopper’s ID from a cookie in the browser into an HTTP header on a tool call made by a managed agent runtime, without the model ever seeing or generating it.
The chat widget cannot set headers on the agent’s tool calls. What it can do is put variables on the agent session through setQueryParameters. The OpenAPI schemas then bind those variables to headers using the x-ces-session-context extension, so the platform injects x-snowplow-session-id and x-snowplow-user-id into every tool request at call time. The model does not know they exist. On the server, the tool handlers read the headers and set domain_sessionid and domain_userid on the Node tracker, so a tool_execution event emitted from the server carries the same session and user as the product_viewed event emitted from the browser. They join on domain_sessionid with no lookup table.
The session variables have no default value, on purpose. A default would quietly fill a missing session ID with another session’s data, and the agent would greet one shopper with someone else’s browsing.
A third variable, a per-turn ID, travels the same way and is what makes the agent’s own events joinable to the conversation.
What building on a managed platform taught us
The tool endpoints are called by Google’s servers, so they need a public HTTPS address, and the full browser-to-agent path can only be verified against a deployed storefront. The repo includes a harness on Snowplow Micro, a local test pipeline, for everything up to that point, and a post-deploy smoke test for the rest. The self-tracking endpoints honor a dry-run header, so the smoke test can probe production without creating events.
The platform’s rich response widgets, the product carousel and product detail cards in the screenshot, have fixed schemas, and the stock ces-messenger component does not render either of them. The storefront ships its own renderer, and the repo captures the widget schemas so the field mapping from catalog results to cards is a checked-in contract rather than folklore.
None of this depends on the storefront being ours. Any agent platform that supports OpenAPI tools and session-scoped variables injected into requests can read Signals the same way, and the storefront side does not know which platform is calling.
Running it yourself
The repository contains the storefront, the agent’s instructions and OpenAPI schemas, optional Terraform using the google_ces_* resources to codify the console build, the BigQuery queries, and an interactive setup script that captures credentials, seeds the tracking plan into your Snowplow organization, publishes the Signals configuration and deploys the storefront. Two guides cover the Snowplow side and the CX Agent Studio side in order.
It is a reference integration for demos and evaluation. It runs on demo data, with a deliberately simple shared-secret auth model on the tool endpoints, and is not hardened for production traffic.
The build is on its reference architecture page, and the code and both setup guides are at github.com/snowplow-industry-solutions/signals-google-cx-agent-studio. To see what Signals computes from your own events, start free: the free tier runs on the real engine, needs no card, and shows an attribute updating against your own traffic in the first session.